Model Capacity
Offline generator
Success rate ↑
Tracking MPJPE ↓
Online generator
Learning humanoid control from monocular human videos offers a scalable way to acquire diverse whole-body behaviors. Yet, existing reconstruction-retargeting-tracking pipelines are limited in system-level scalability by separately optimized intermediate stages and cannot directly optimize reference motion executability using downstream tracking feedback.
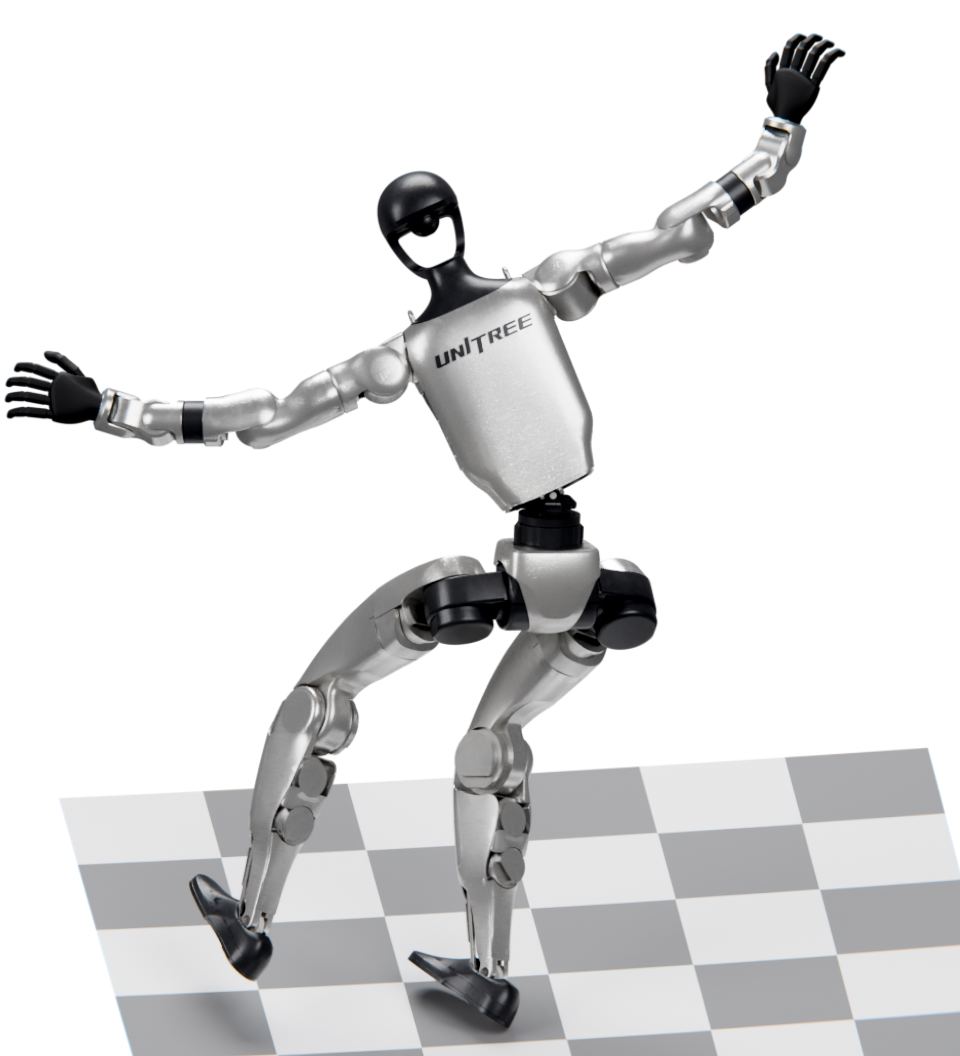
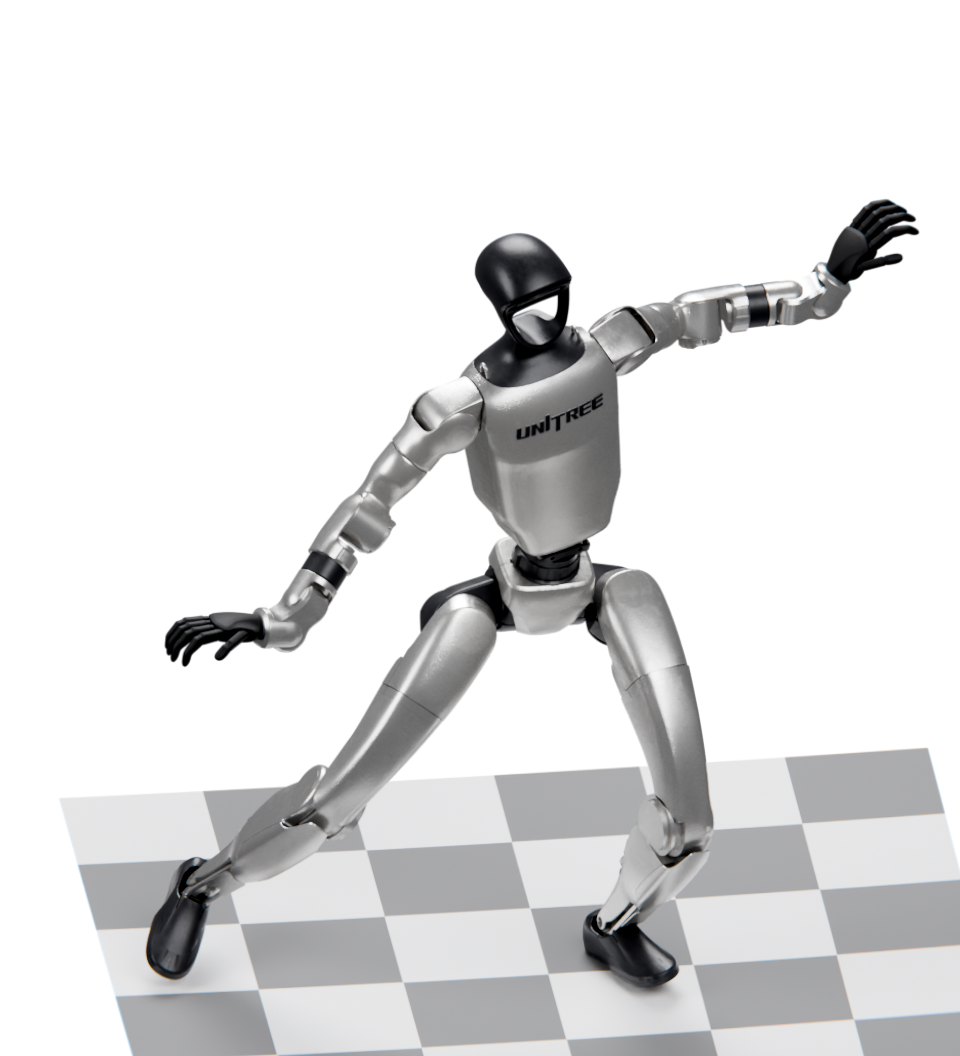
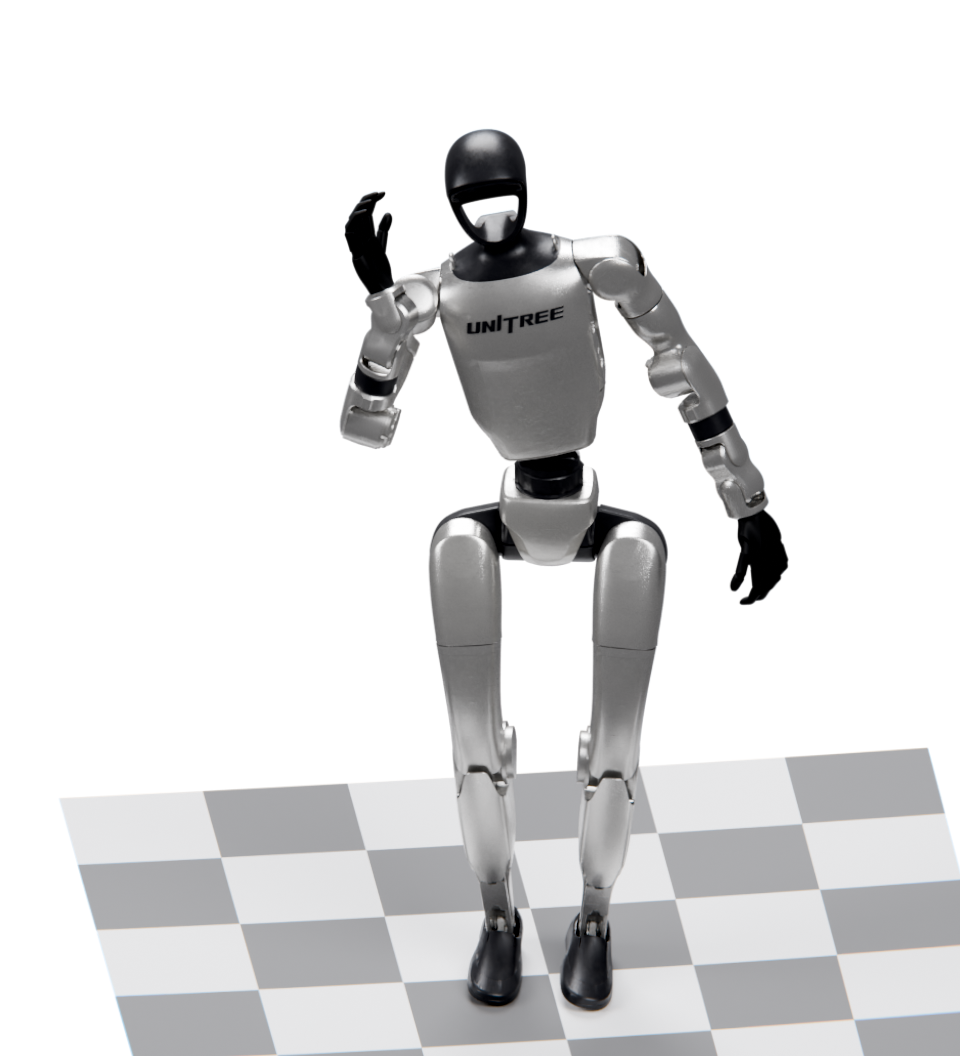
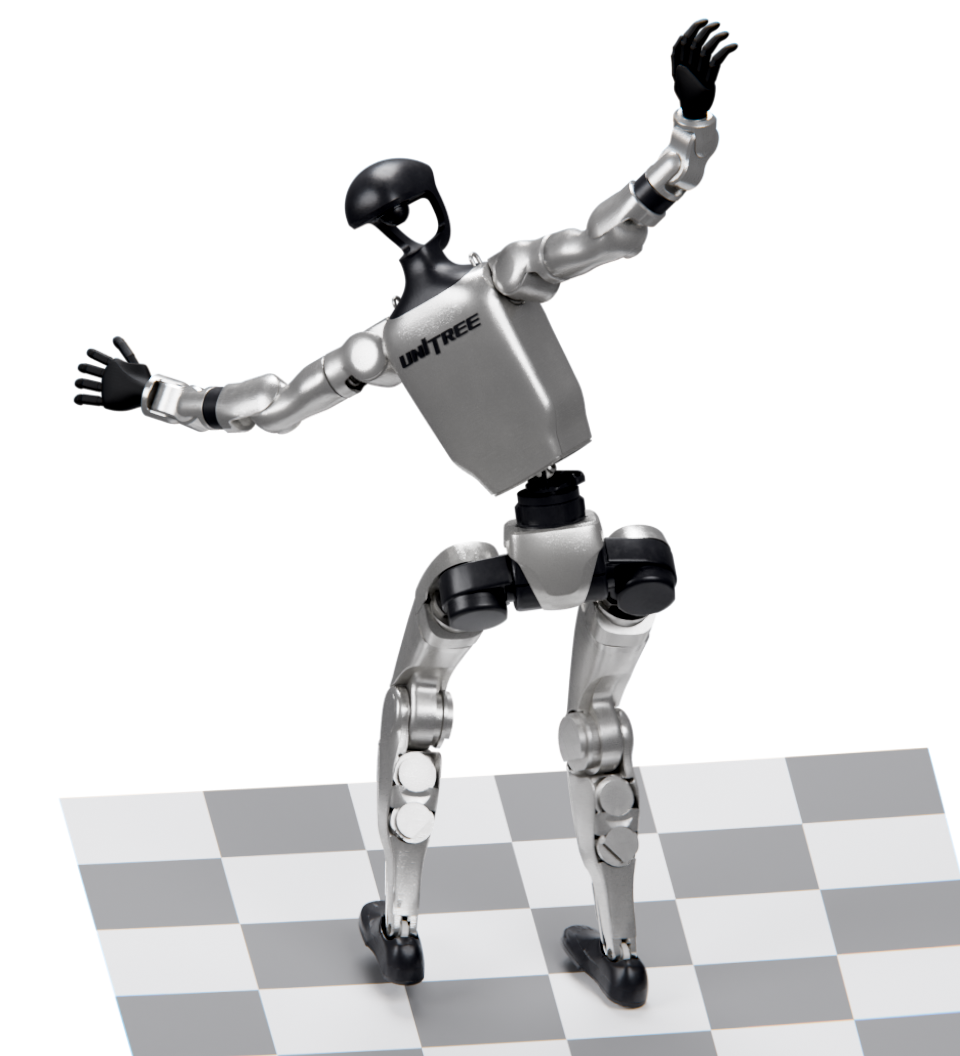
We present ViT-H, a video-to-humanoid control framework following a generation-and-tracking paradigm. ViT-H directly generates humanoid reference motions from videos with a diffusion model, bypassing human motion reconstruction and retargeting, and uses motion-tracking outcomes to post-train the generator with direct preference optimization. We further introduce an autoregressive variant that enables real-time humanoid video teleoperation with sub-500 ms latency.
Extensive experiments on the Unitree G1 demonstrate that ViT-H outperforms state-of-the-art reconstruction-retargeting-tracking pipelines in both motion quality and executability. We further show that ViT-H scales favorably with model size and with both pre-training and post-training data scale, while motion-tracking feedback consistently improves executability across different motion trackers.
Real-world highlights
RealSense D455 · RGB only
250ms on average
Generation and tracking
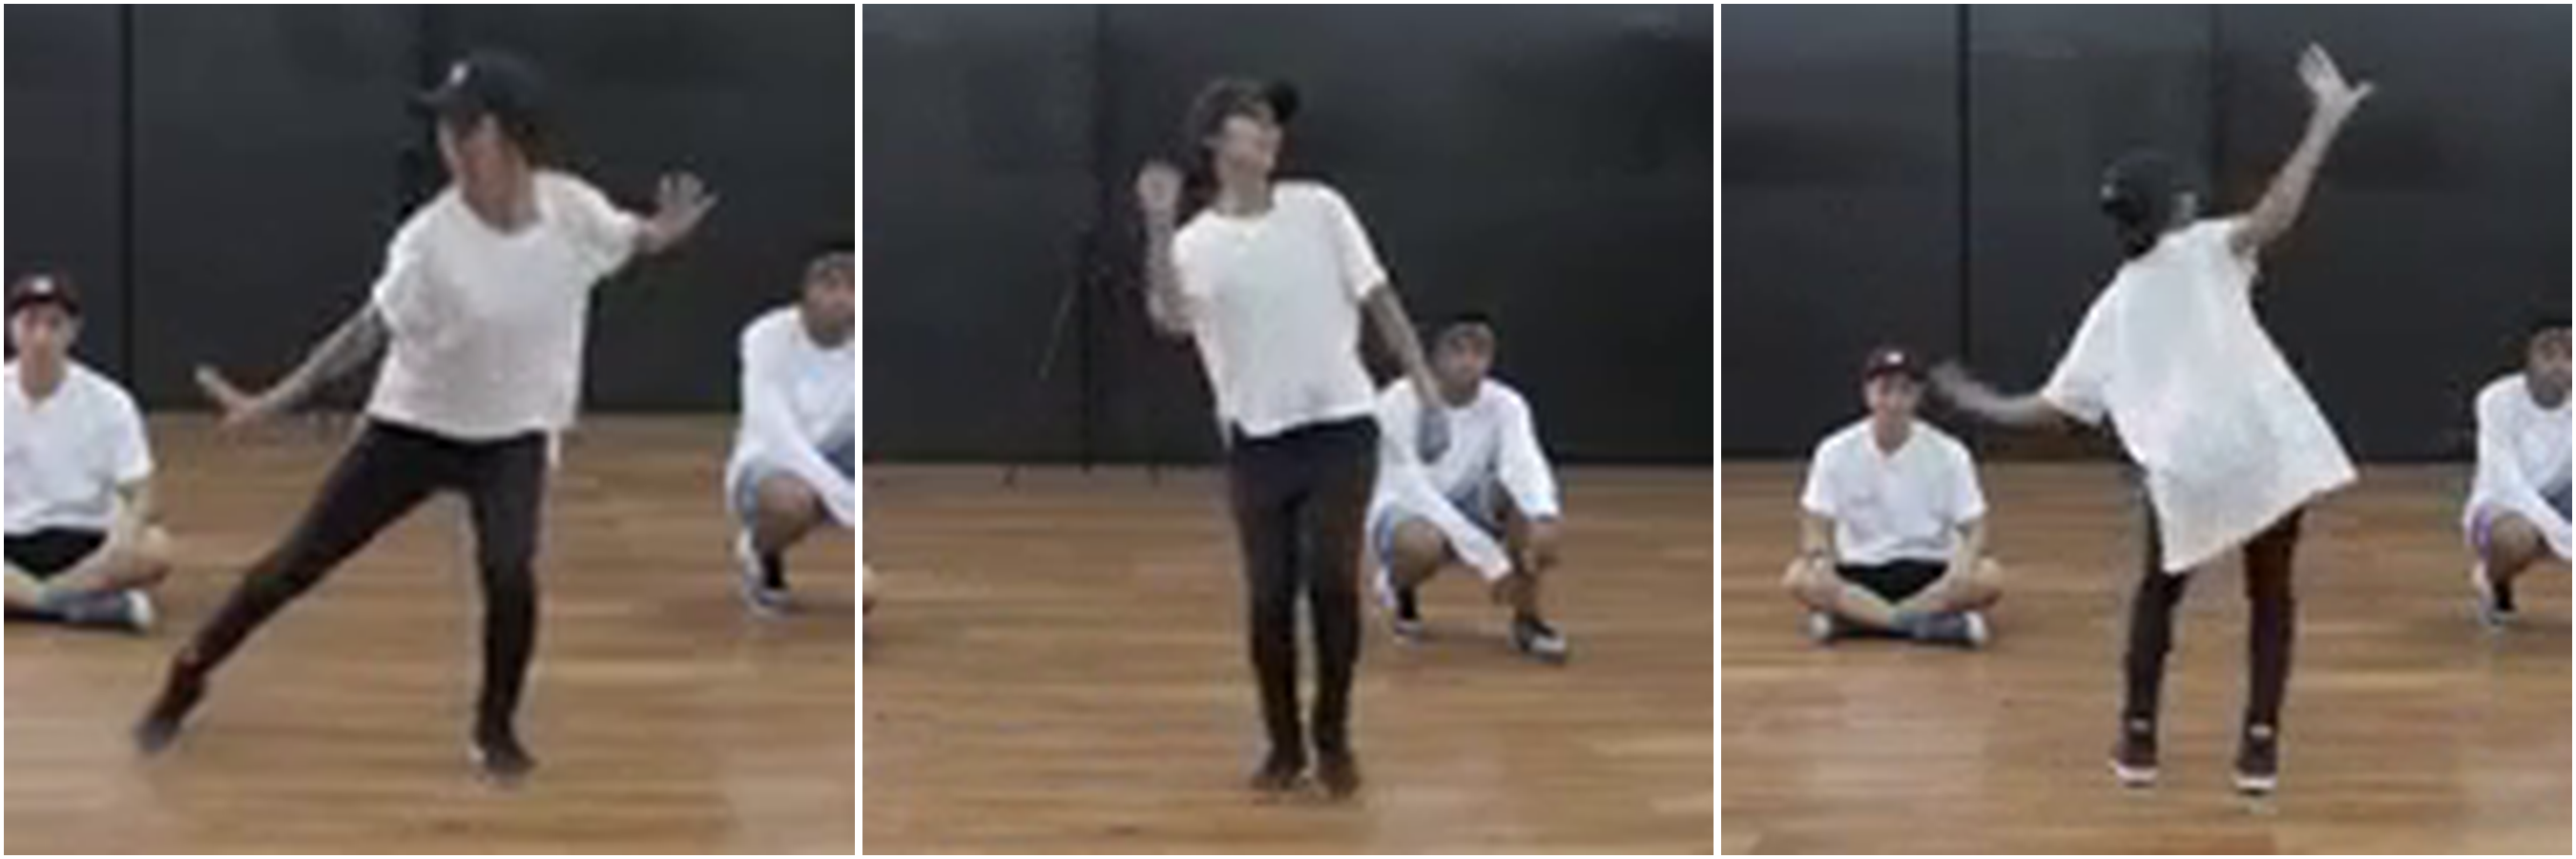
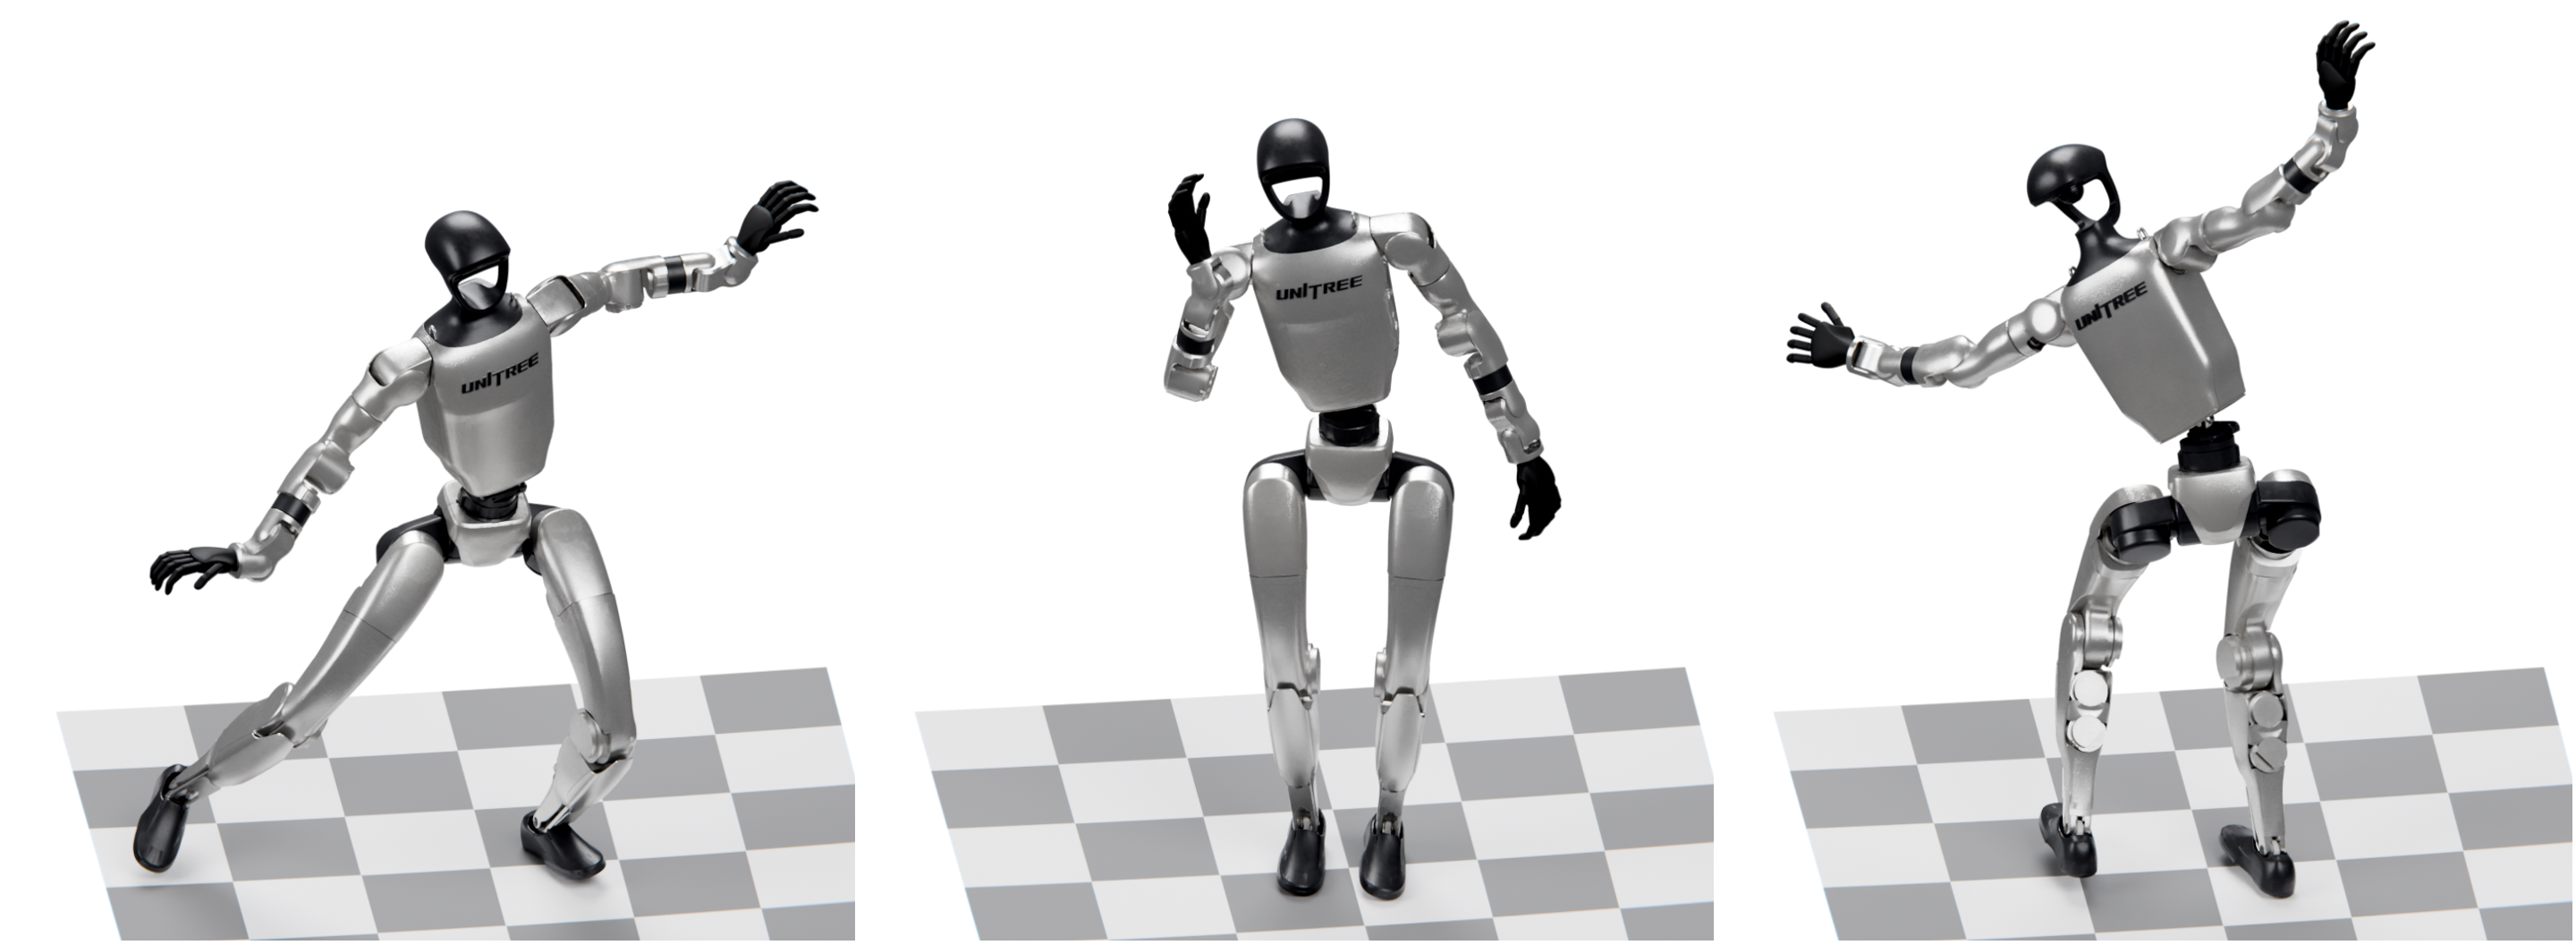
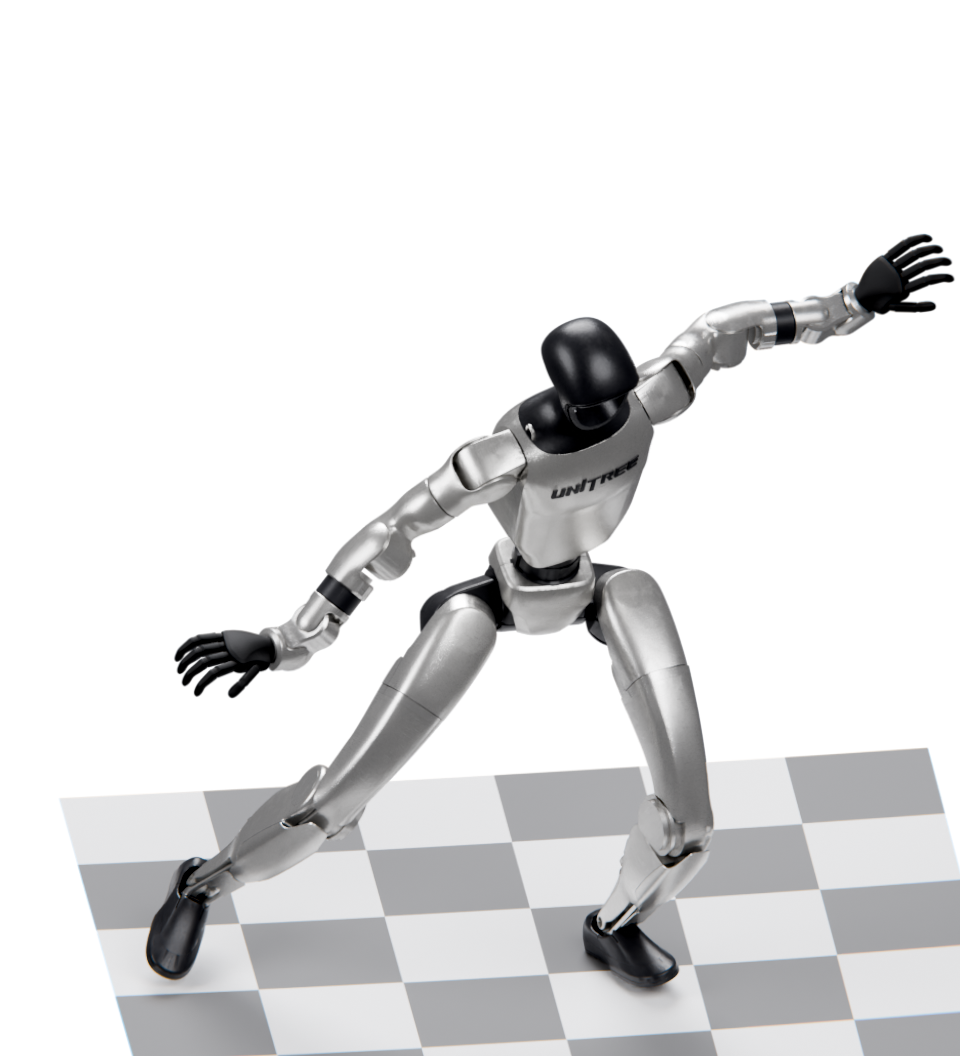
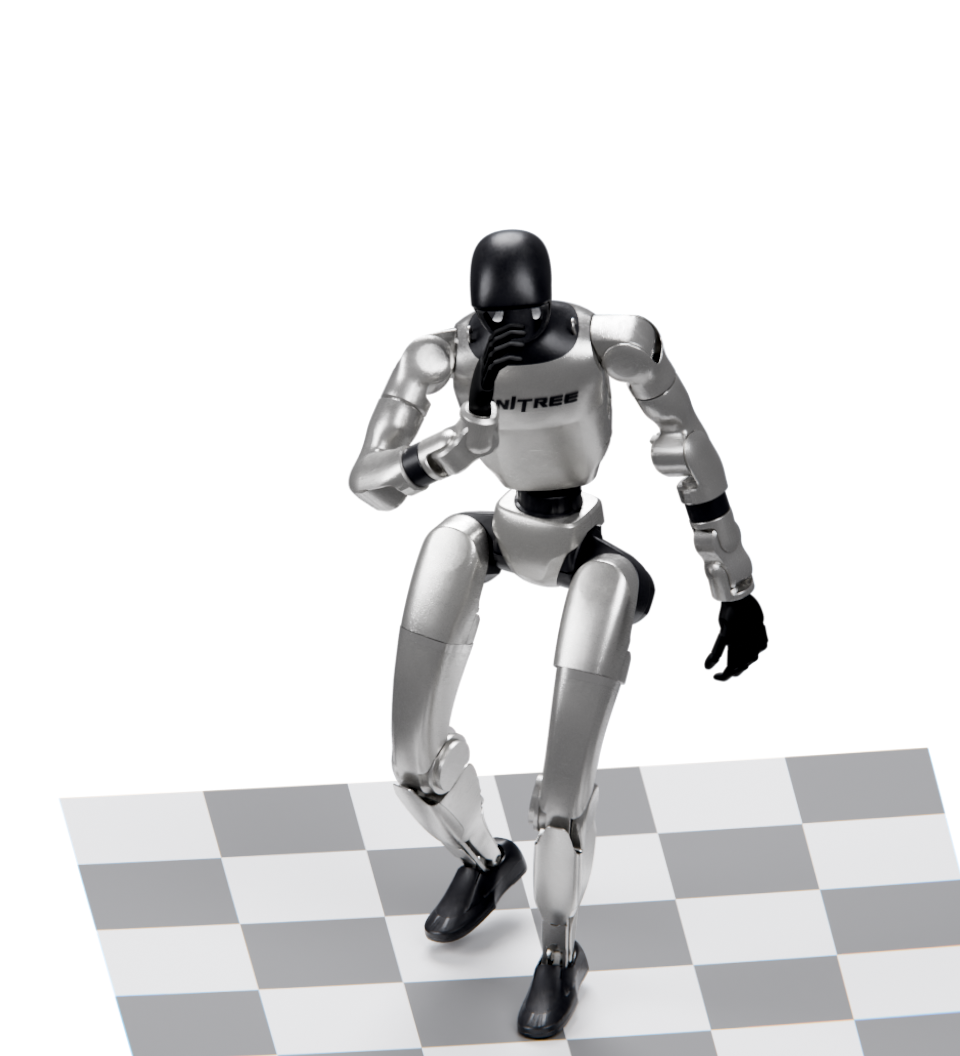
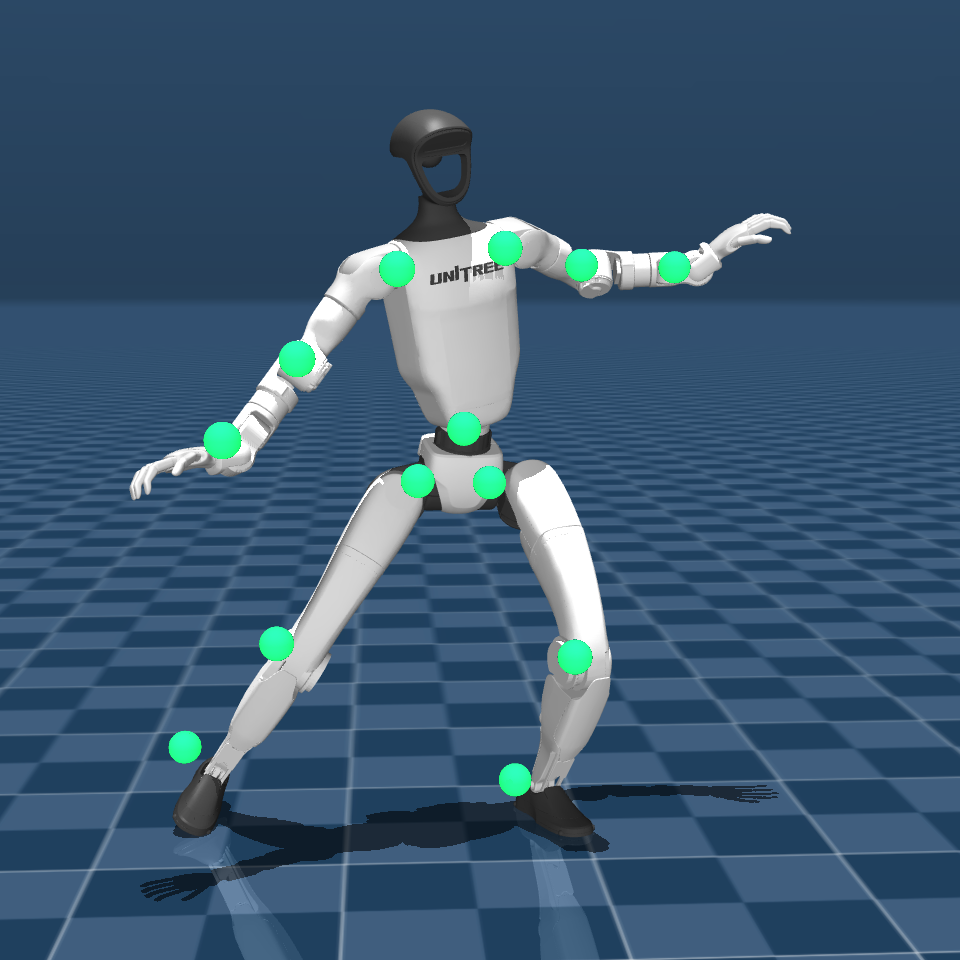
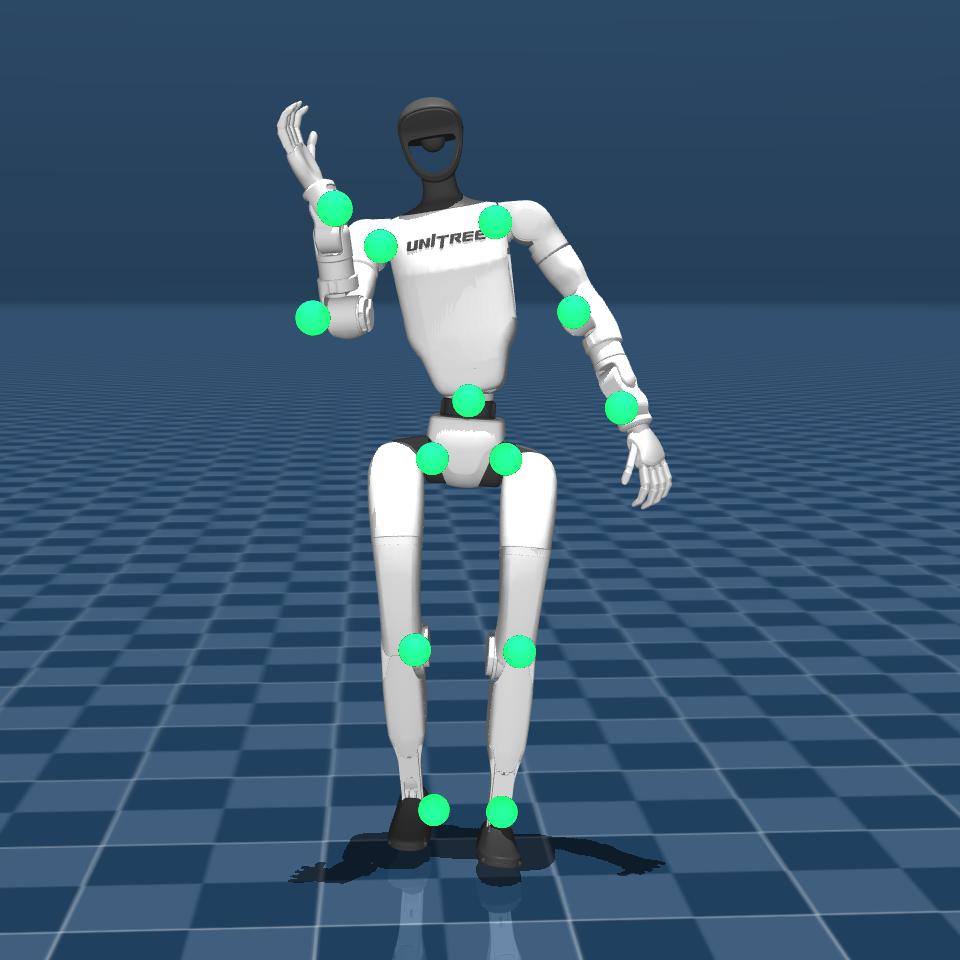
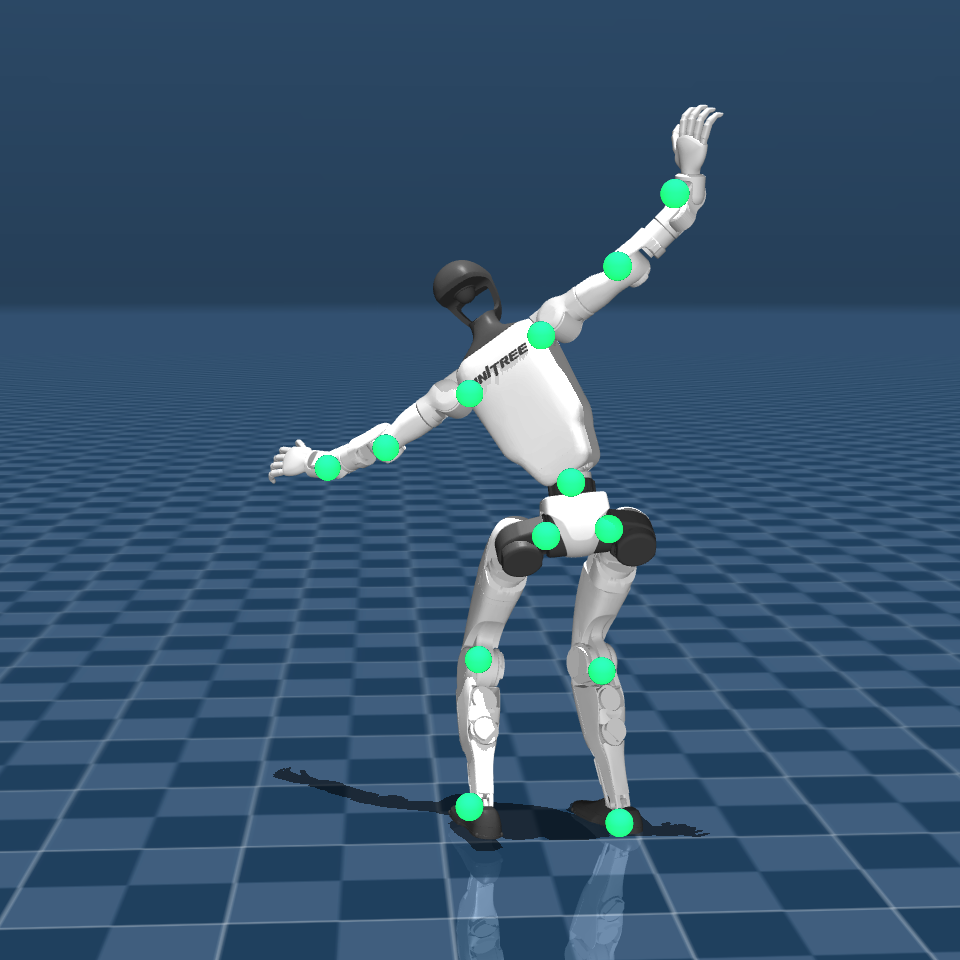
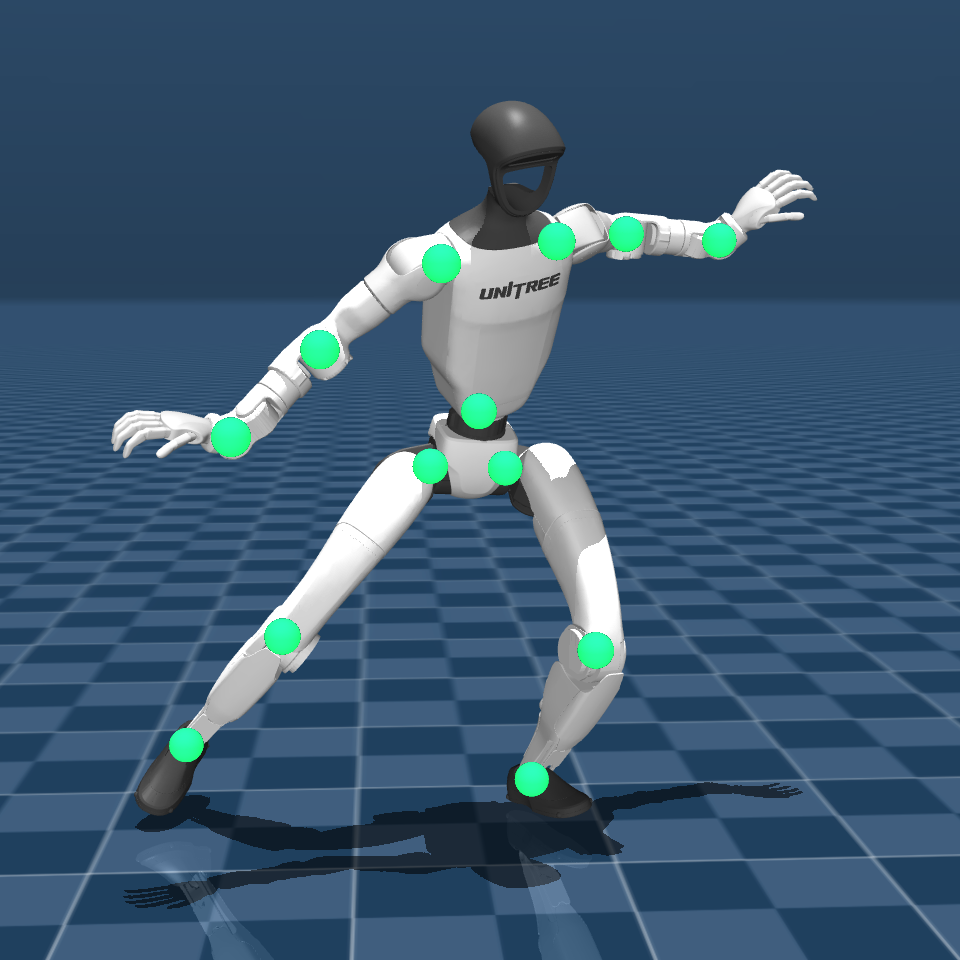
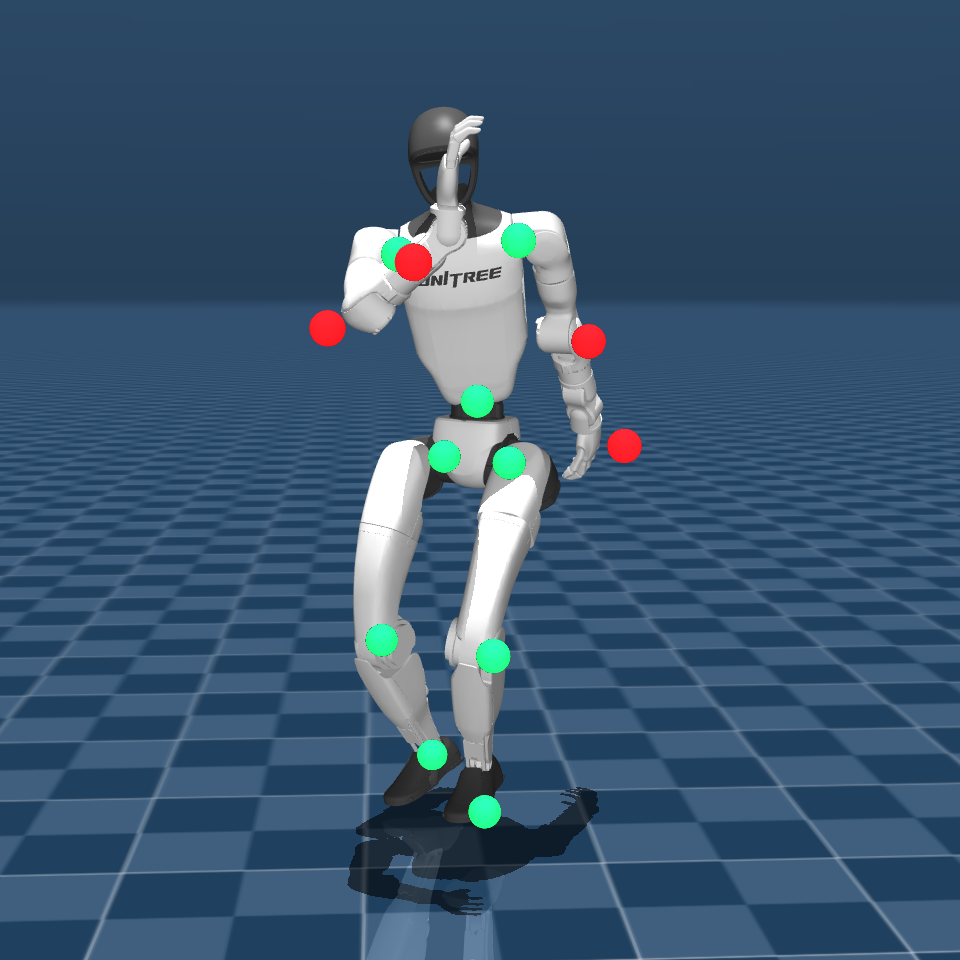
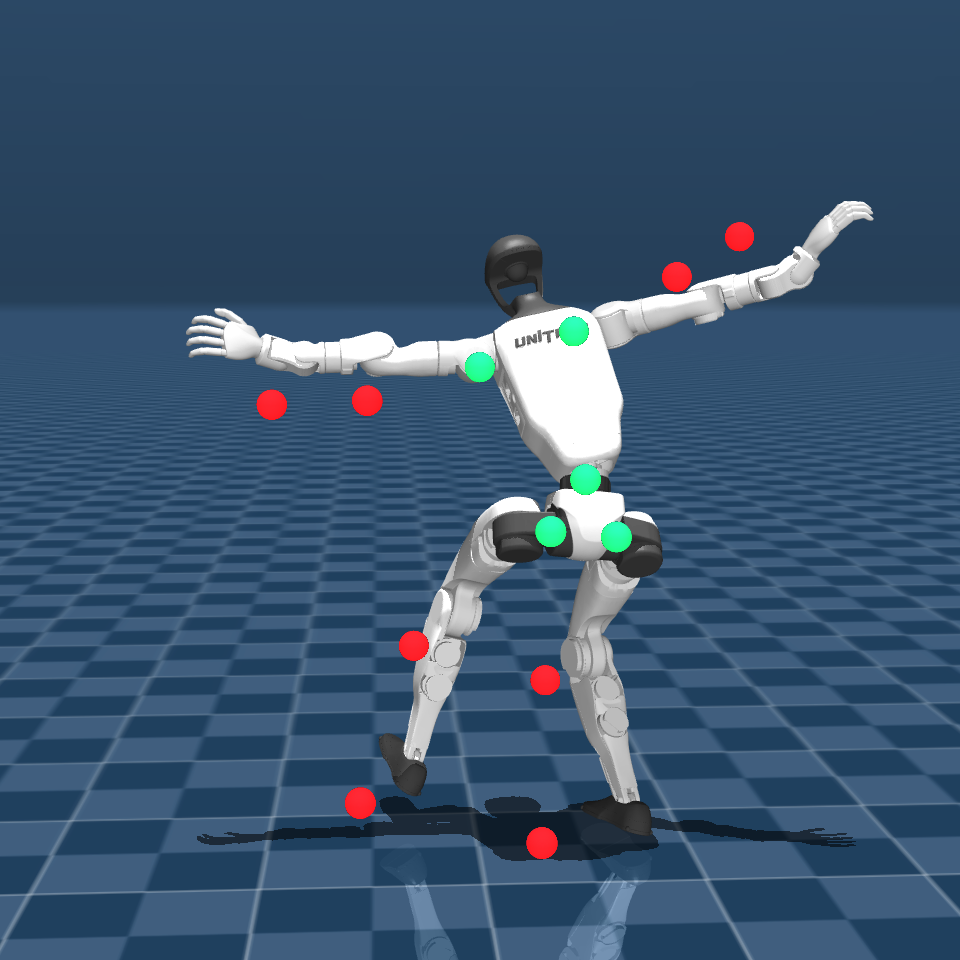
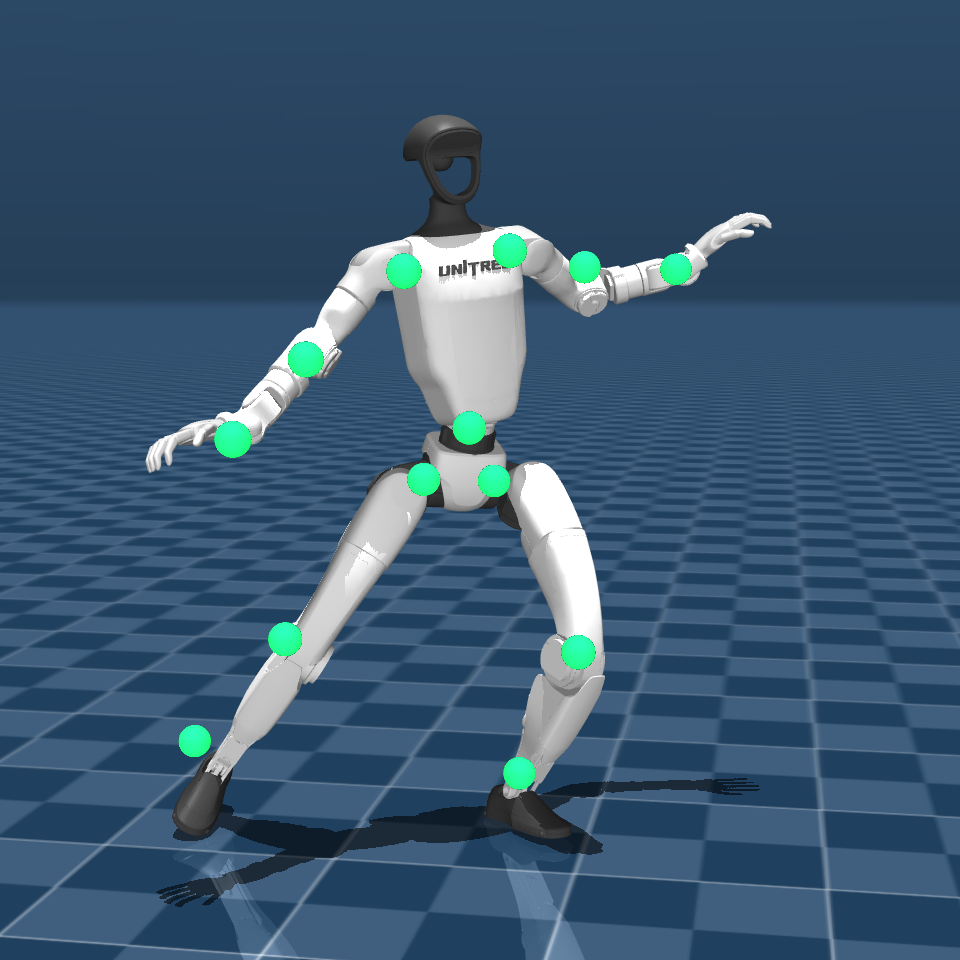
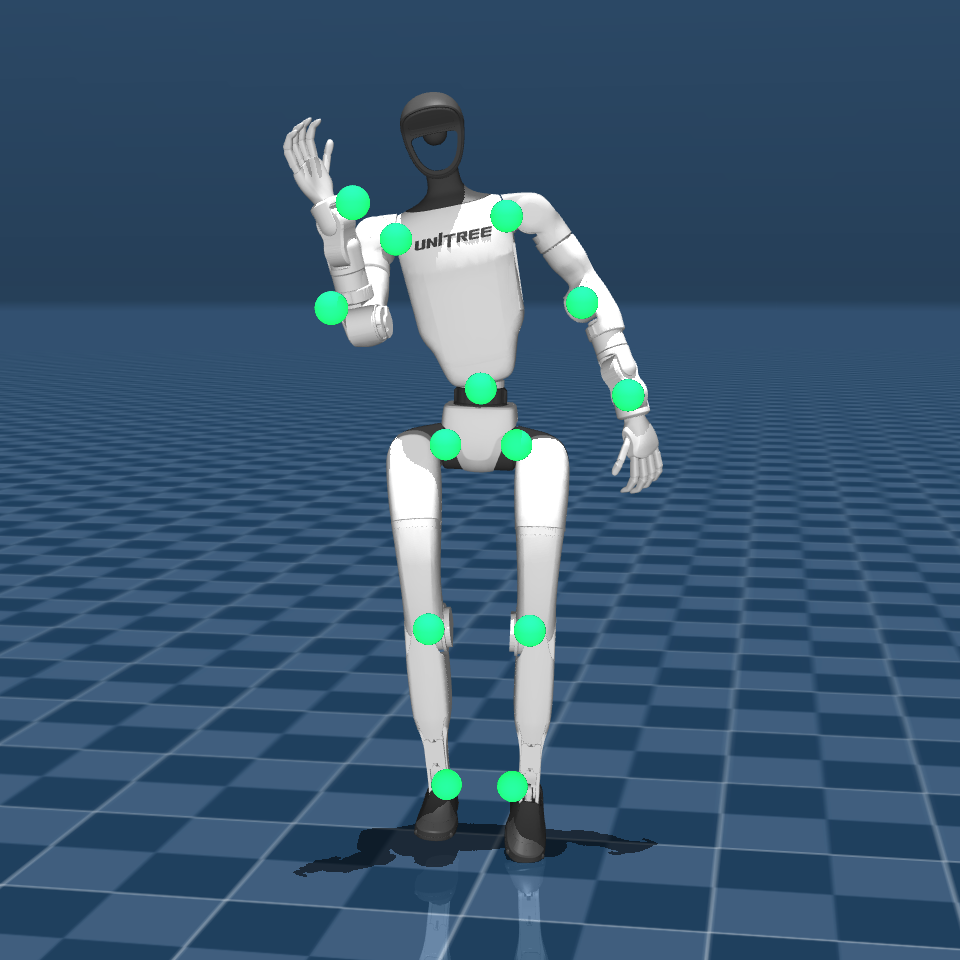
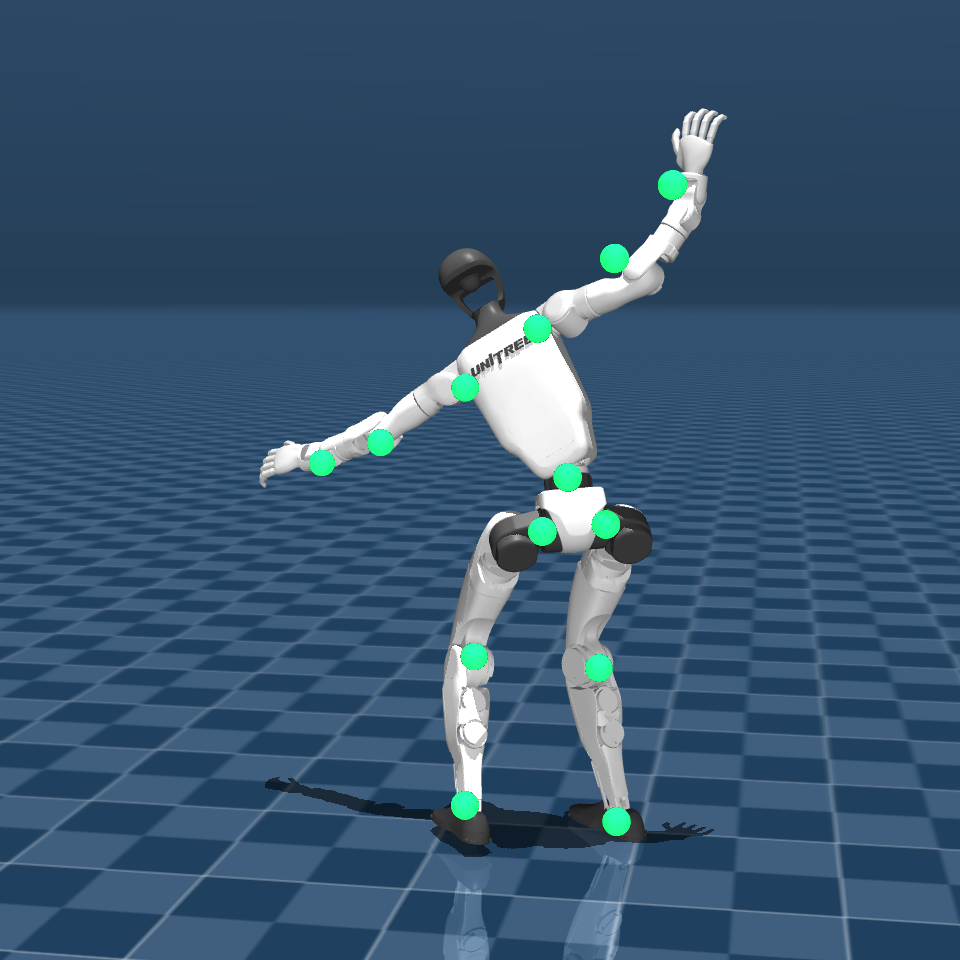
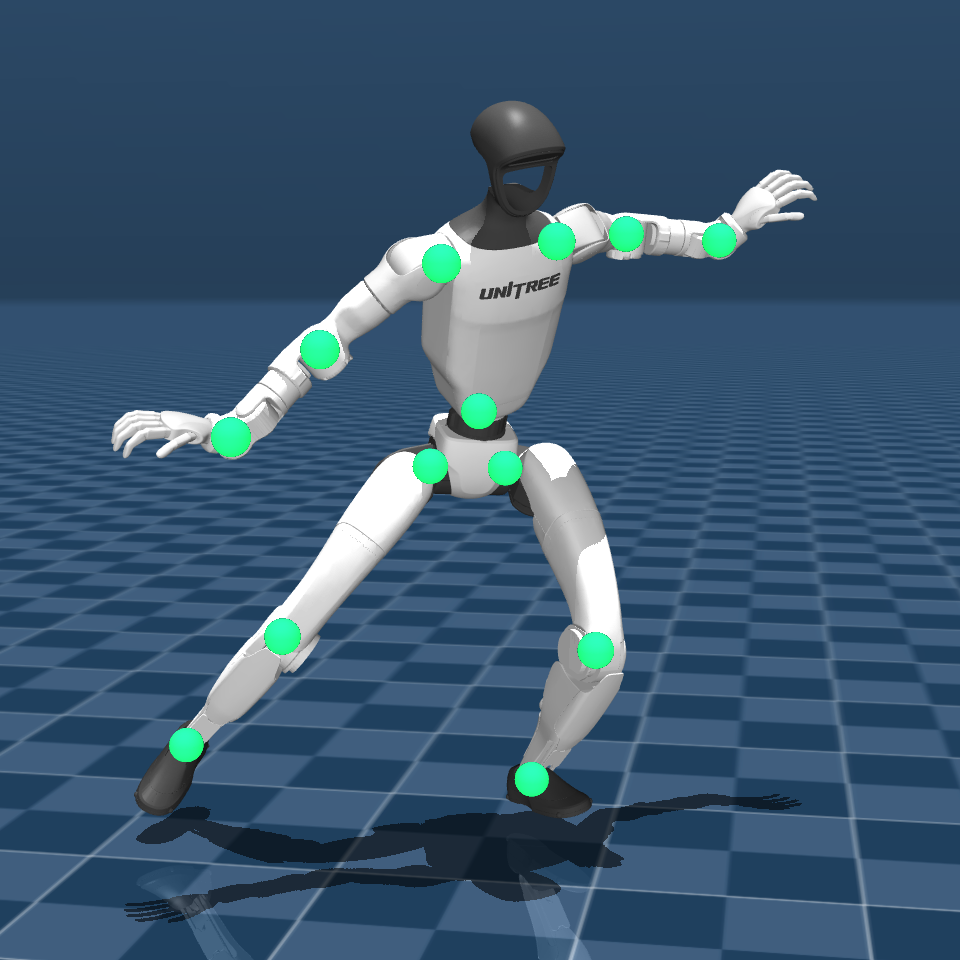
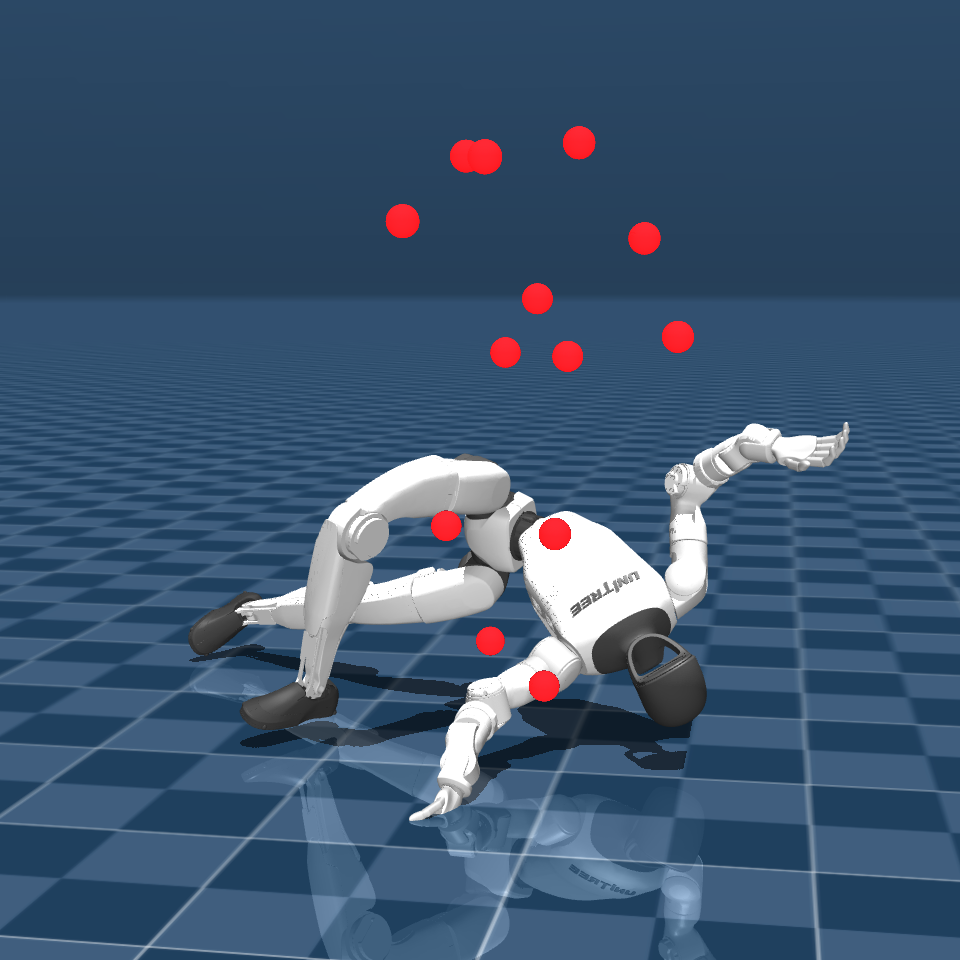
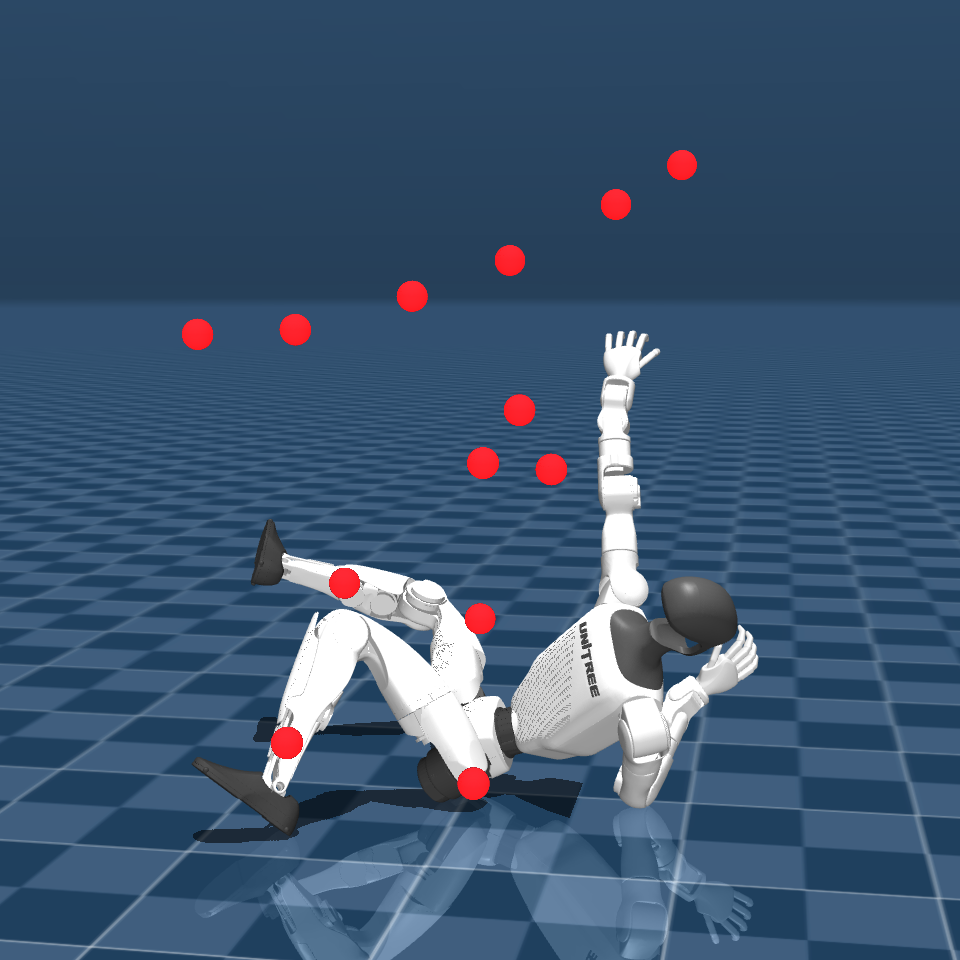
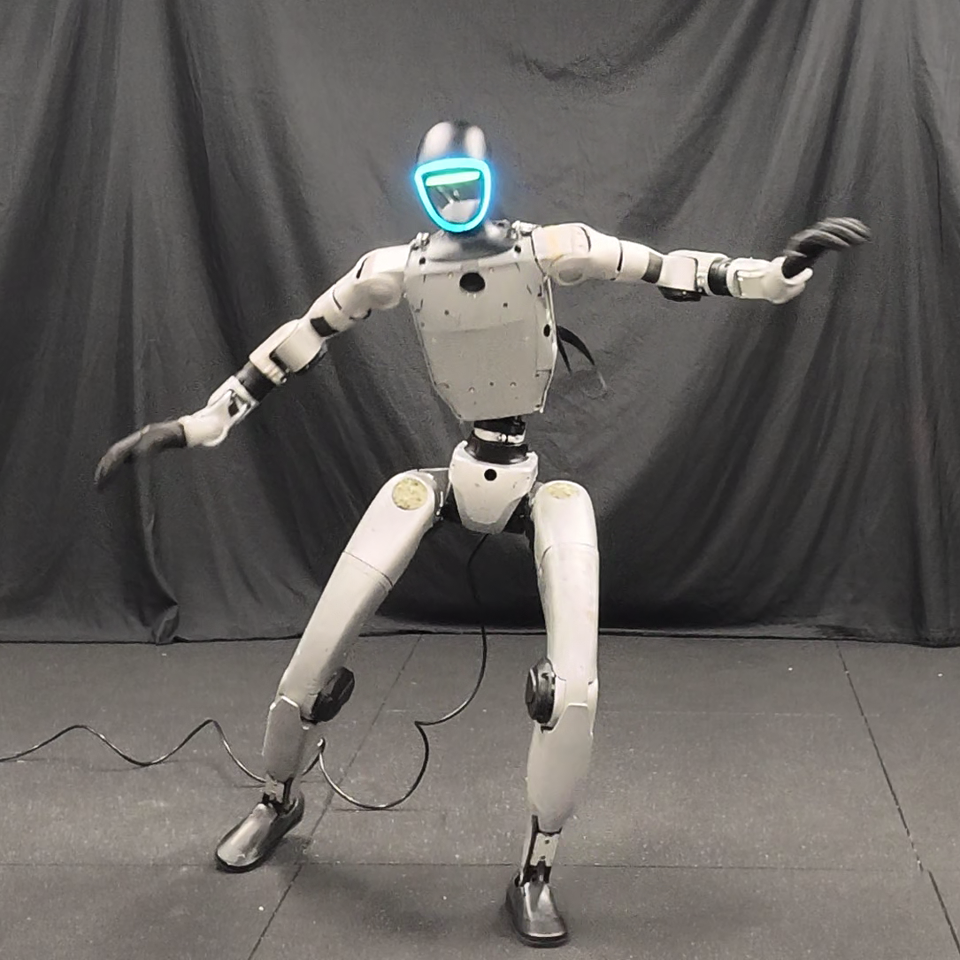
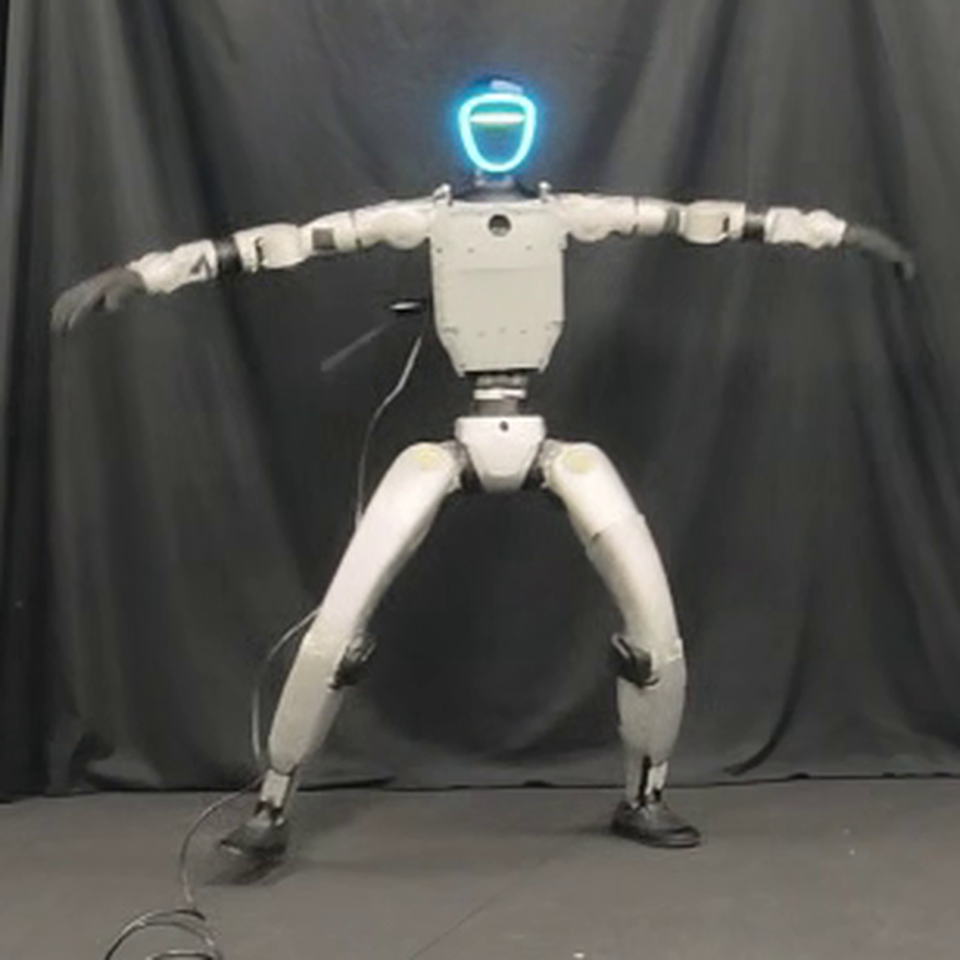
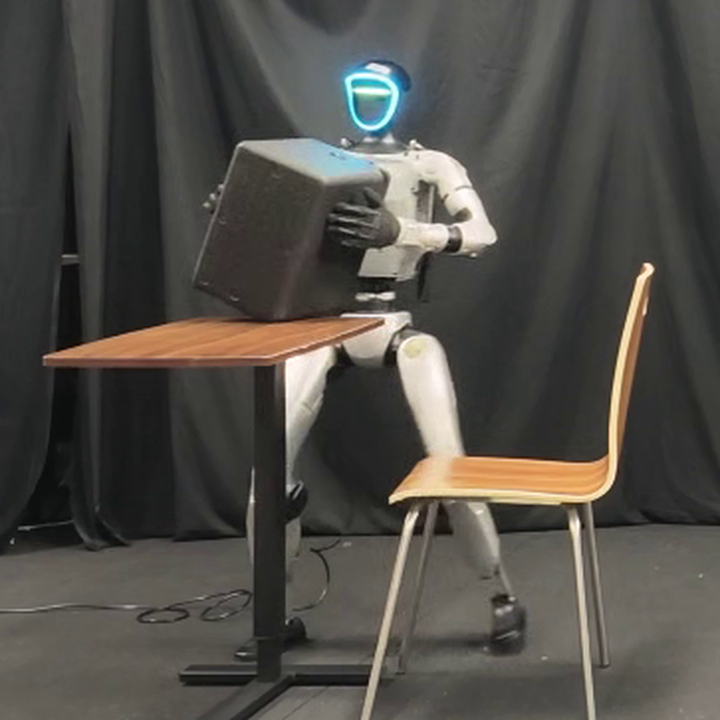
Real-world deployment
Experimental results
Offline generator
Online generator
Offline generator
Online generator
Offline generator
Online generator
Offline generator
Online generator
Offline generator
Online generator
Offline generator
Online generator
@article{he2026vith,
  title={ViT-H: Generative Video-To-Humanoid Control with Motion Tracking Feedback},
  author={He, Zimo and Bian, Tianyi and Yang, Zizhong and Li, Hongjie and Jiang, Nan and Cui, Jieming and Jia, Baoxiong and Wang, Yizhou and Huang, Siyuan and Zhu, Yixin},
  journal={arXiv preprint arXiv:xxxx.xxxxx},
  year={2026}
}